TOP-GEO

Your brand, in the answers they get.

People ask models now, not ten blue links. We measure whether those answers mention you, cite you, or tell someone to use you.

Ten named engines. Same prompt panel. A monthly slice you can defend in a meeting — not a screenshot of one lucky ChatGPT reply, and not a rank nobody can sell.

  • Mentions / 1,000 queries
  • 10 answer engines
  • Monthly slice
Dashboard

GEO / AEO

Neural search does not rank a URL. It names a brand — or it names someone else.

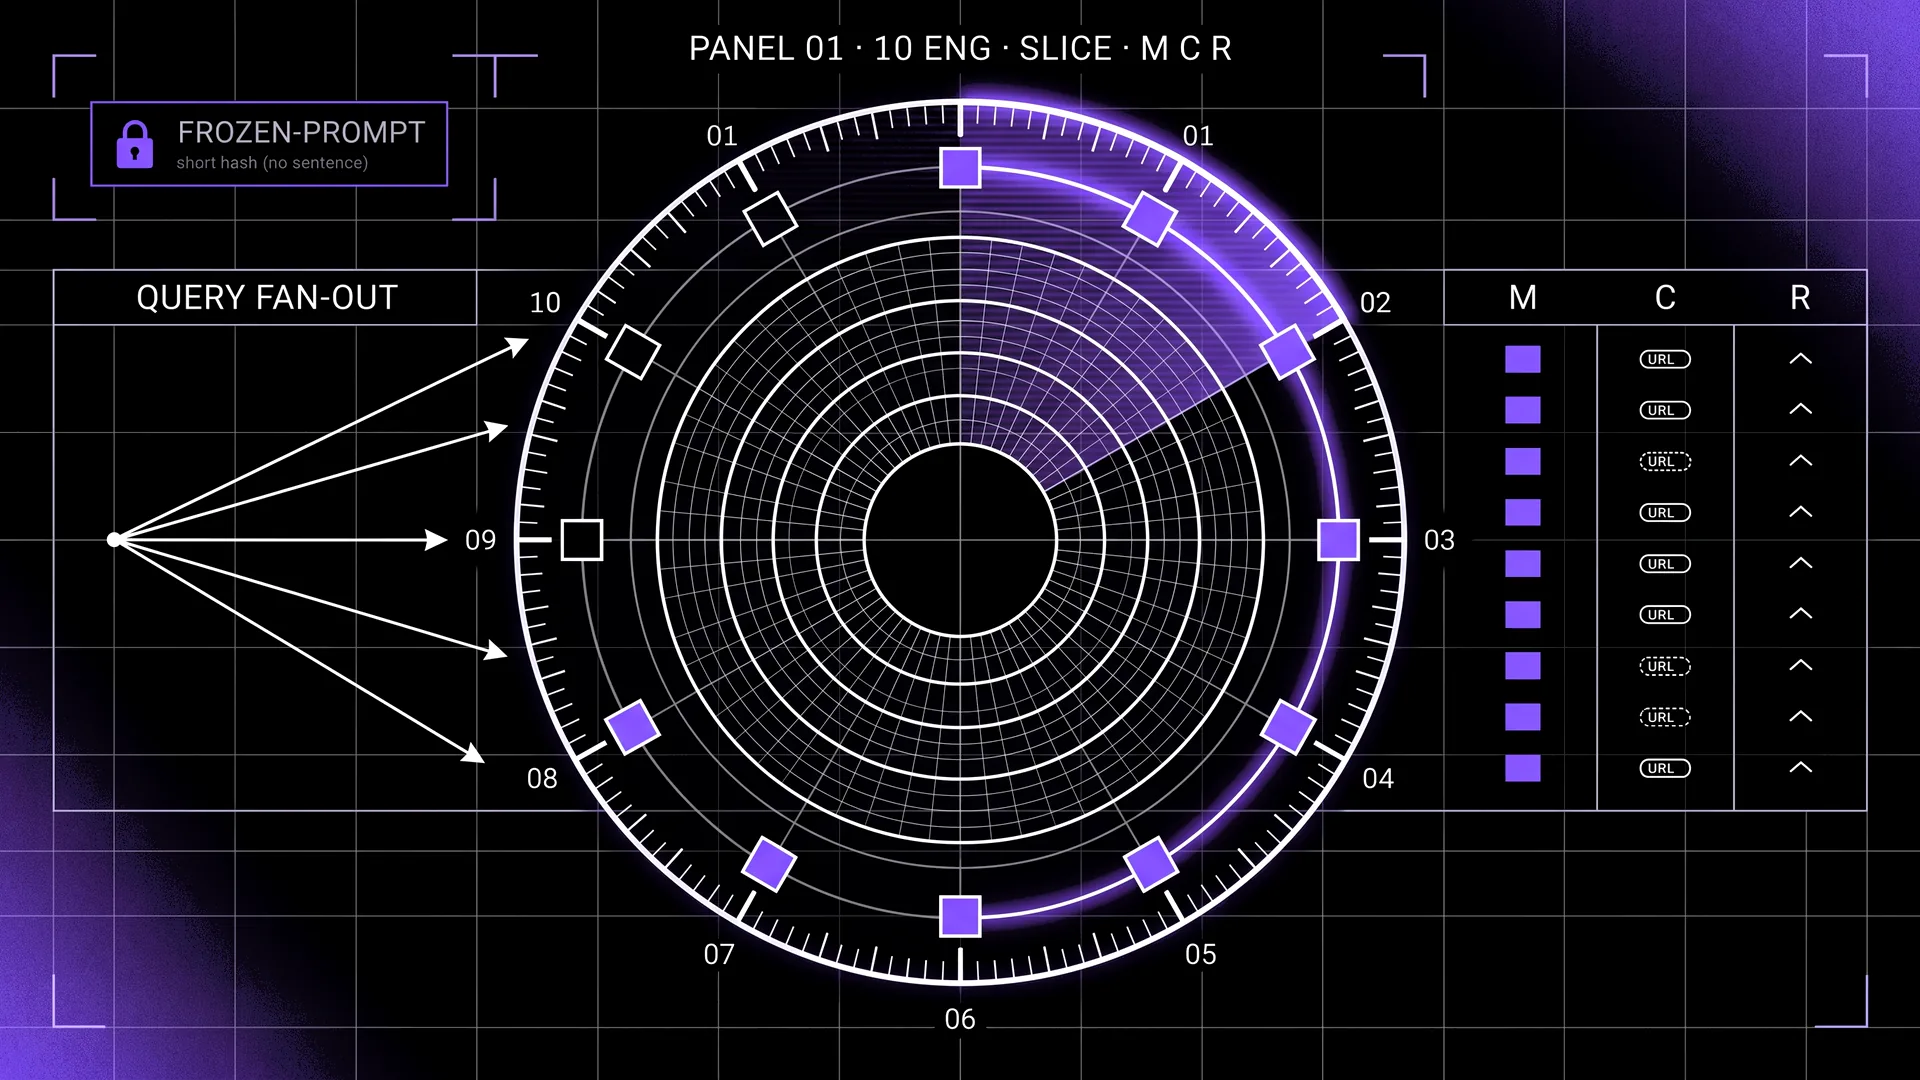
We run a frozen prompt set against ten consumer engines and score three outcomes that the market keeps mixing up: mention, citation, and recommendation. Share of voice and share of answer are always against named peers, on the same panel, on the same date.

Bot access and llms.txt are hygiene. If a crawler cannot fetch the same public HTML a person sees, there is nothing honest to cite. That is not a ticket into ChatGPT, and we will not sell it as one.

On the desk

  • Prompt tracking across ten engines
  • Query fan-out — the splits models actually run
  • Citation URLs: owned, competitor, earned
  • Mention, citation, recommendation — three columns
  • Share of voice, share of answer, and position in the reply
  • Markets and language set before the first prompt
All services
Circular HUD plate: ten numbered engine stations on a rangefinder, a query fan-out, and three readout columns M, C, and R.

SEO

Blue links still move demand. Neural answers grow beside them, not instead of a crawlable site.

Google and Yandex remain the index most teams already pay to understand. We keep technical health, on-page facts, and Search Console as a well for prompts — a bridge, not a GEO rank wearing a Google badge.

A page that models cannot fetch is a page neither classic search nor answer engines can use. Hygiene first. Then the monthly neural slice. Then the next edit.

On the desk

  • Technical and on-page SEO for Google and Yandex
  • Search Console as a source of real queries
  • Sitemaps and indexation that bots can follow
  • Content that is extractable, not stuffed
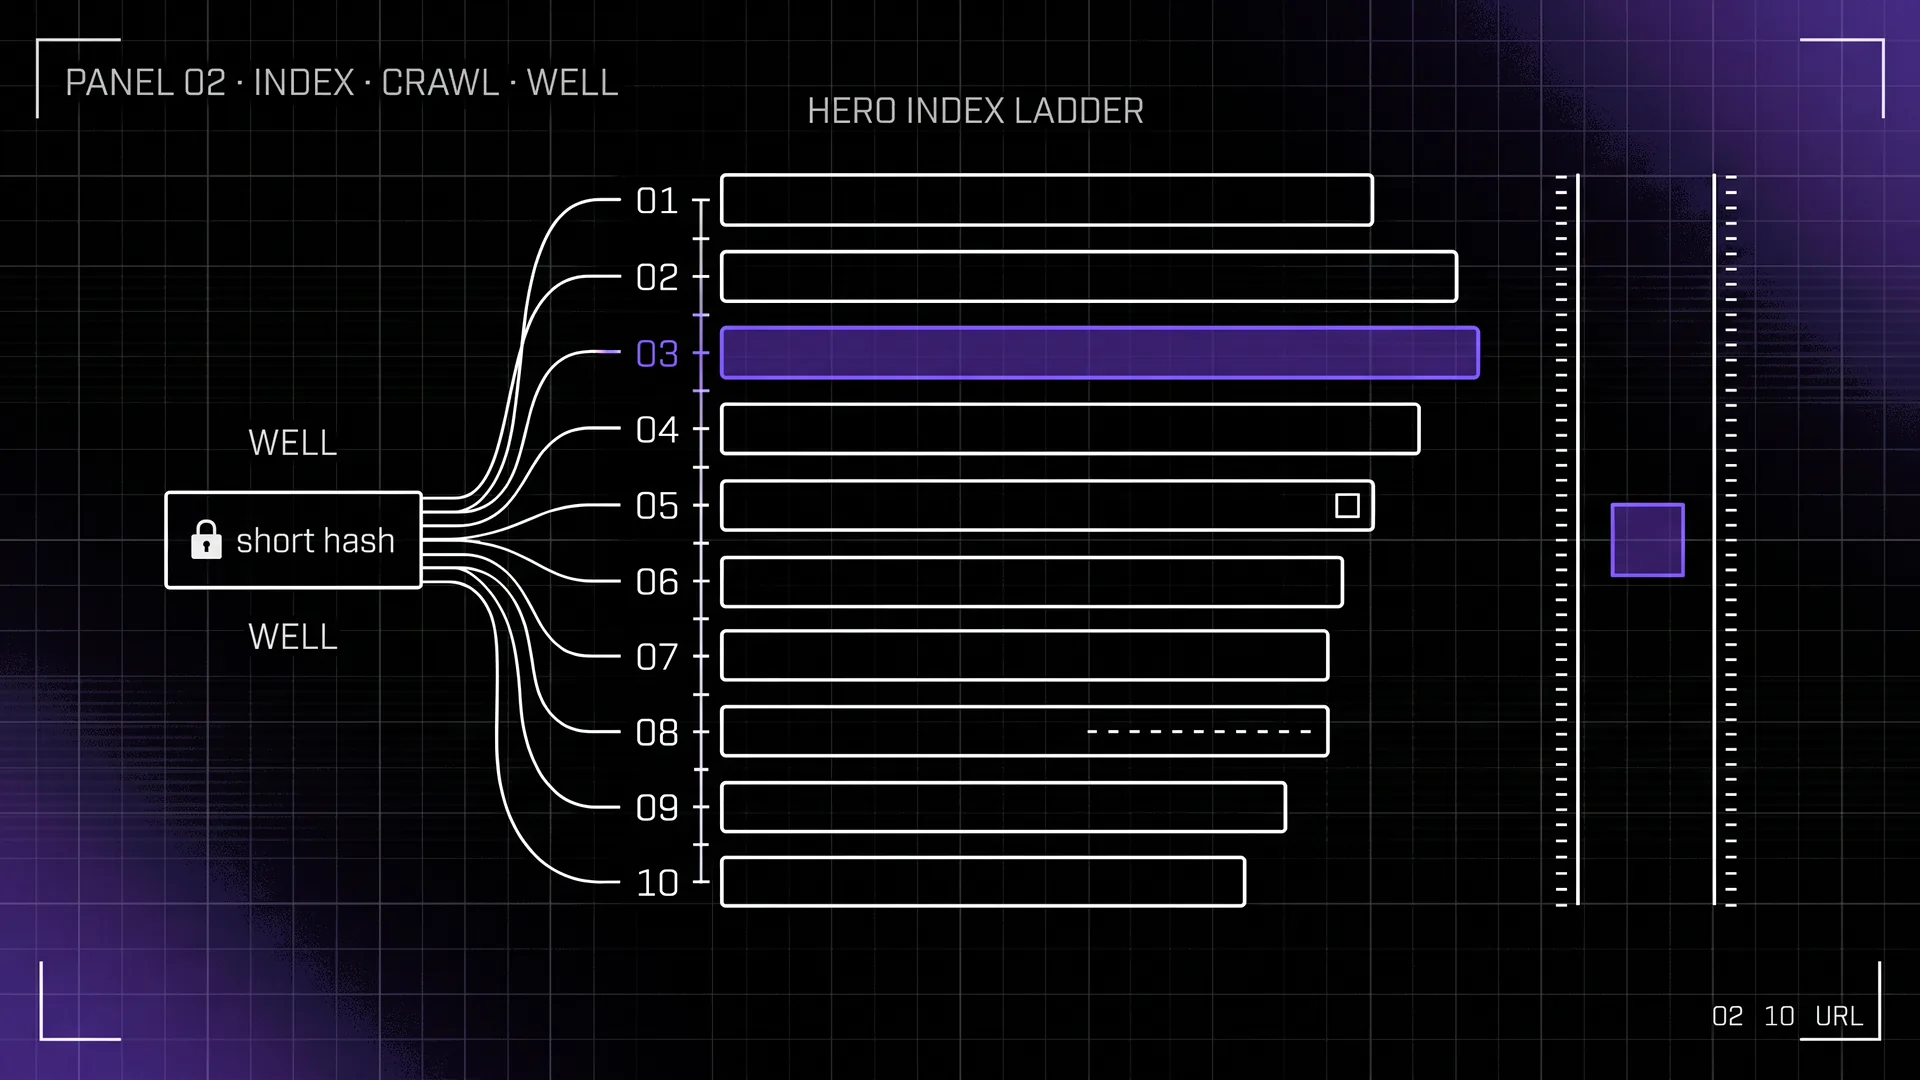
Index-ladder HUD: ten crawl rungs, a query well, and a small answer cell beside the stack.

Content

Models lift spans they can quote. We write for those spans, then a human signs off.

AEO drafts are built around dated, consistent, extractable facts — not FAQ spam as a ranking stunt. Schema and a canonical facts page help a retriever join the entity. They are not a ticket into any allocator.

Human-in-the-loop is the product, not a disclaimer. Autonomous draft is not autonomous publish. The approved URL is what the crawler will actually fetch next month.

On the desk

  • GEO readiness audit and a ranked fix list
  • AEO generation with human approval
  • CMS or feed publish of the signed-off asset
  • JSON-LD hygiene and a source-of-record page
  • No FAQPage spam sold as a ChatGPT trick
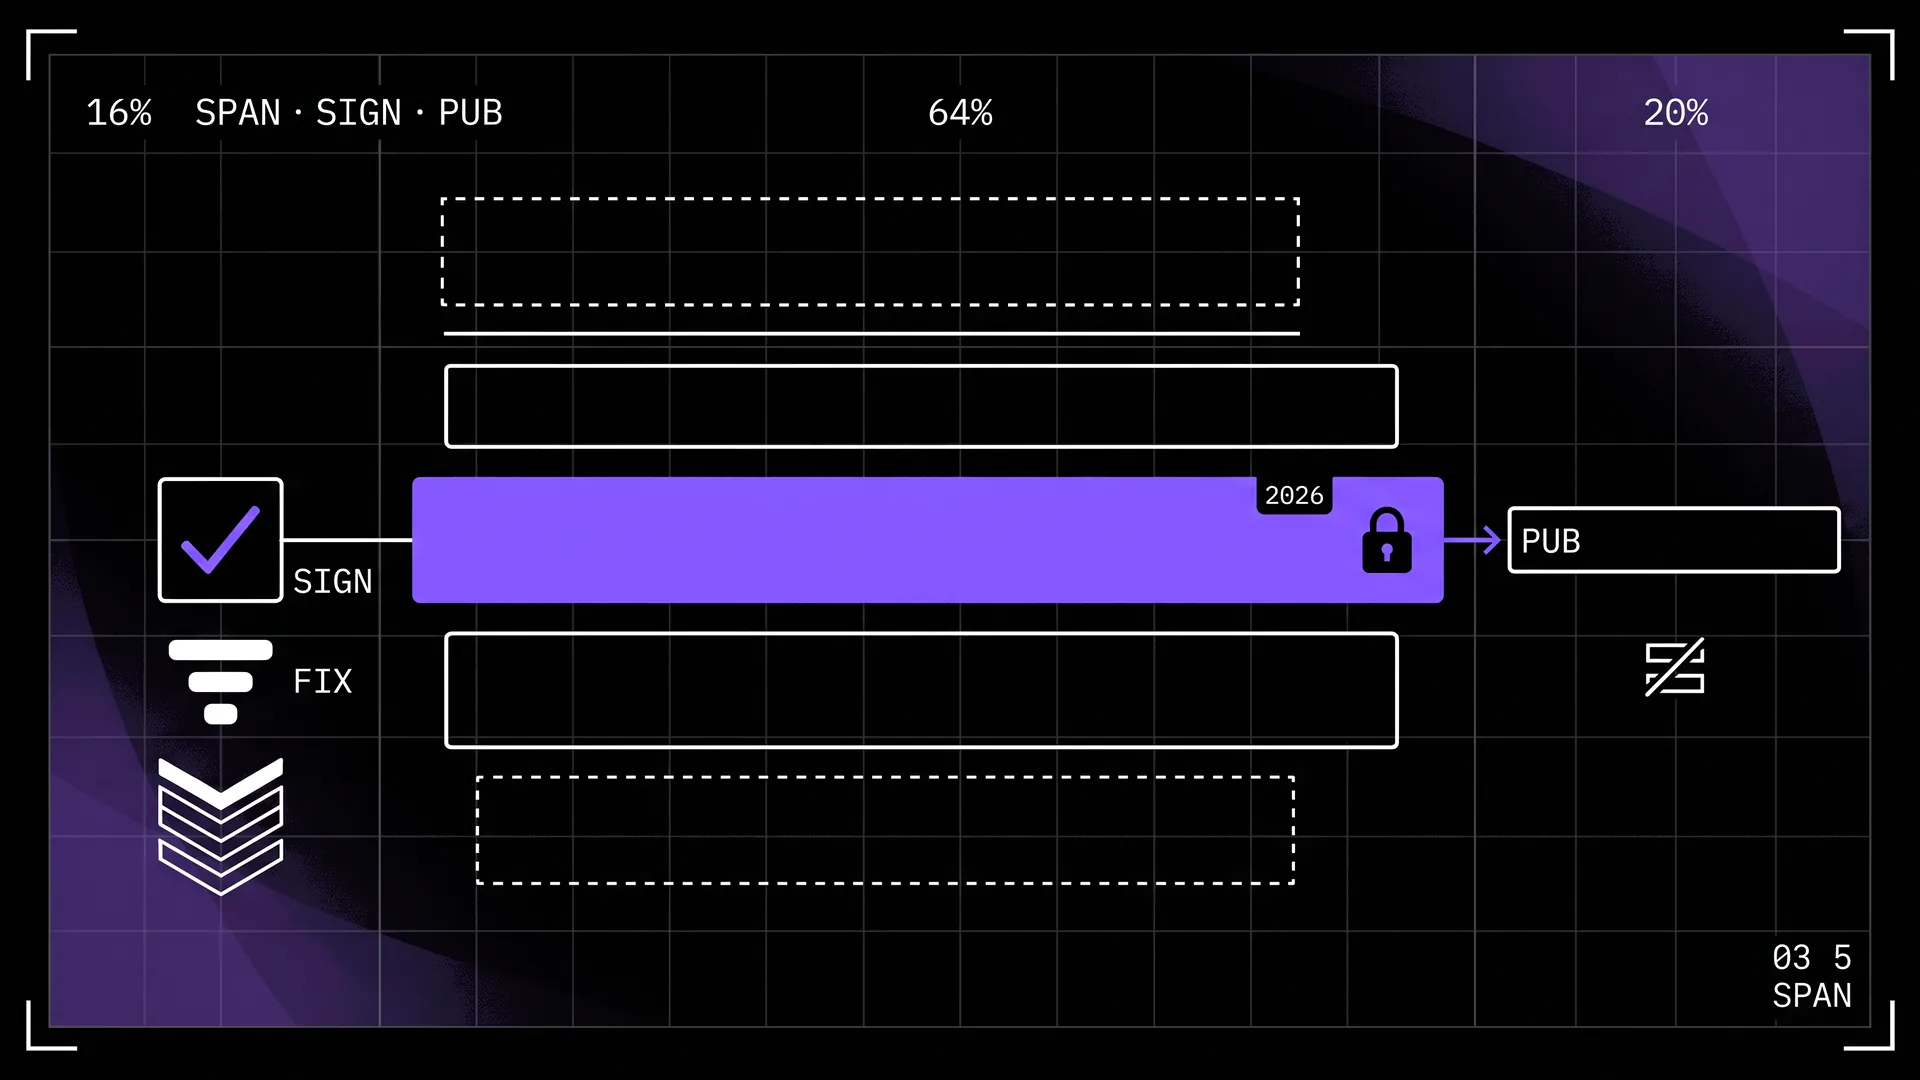
Teletype HUD: five extractable spans, the middle one signed and published.

Analytics

A slice you can defend: same prompts, ten engines, three columns. Not a fake ChatGPT rank.

Visibility is not revenue. When we connect a slice to sessions, the method sits on the label. GA4 undercounts AI referrers; we do not invent last-click GEO ROI to fill the gap.

Alerts fire when mention or citation share crosses a threshold you set. APIs and BI connectors pull the same numbers as the dashboard. Cookieless AI-referrer logs stay off the analytics cookie.

On the desk

  • Monthly slice with honesty badges
  • Alerts on mention and citation share
  • REST API and BI connectors
  • Cookieless AI-referrer traffic from logs
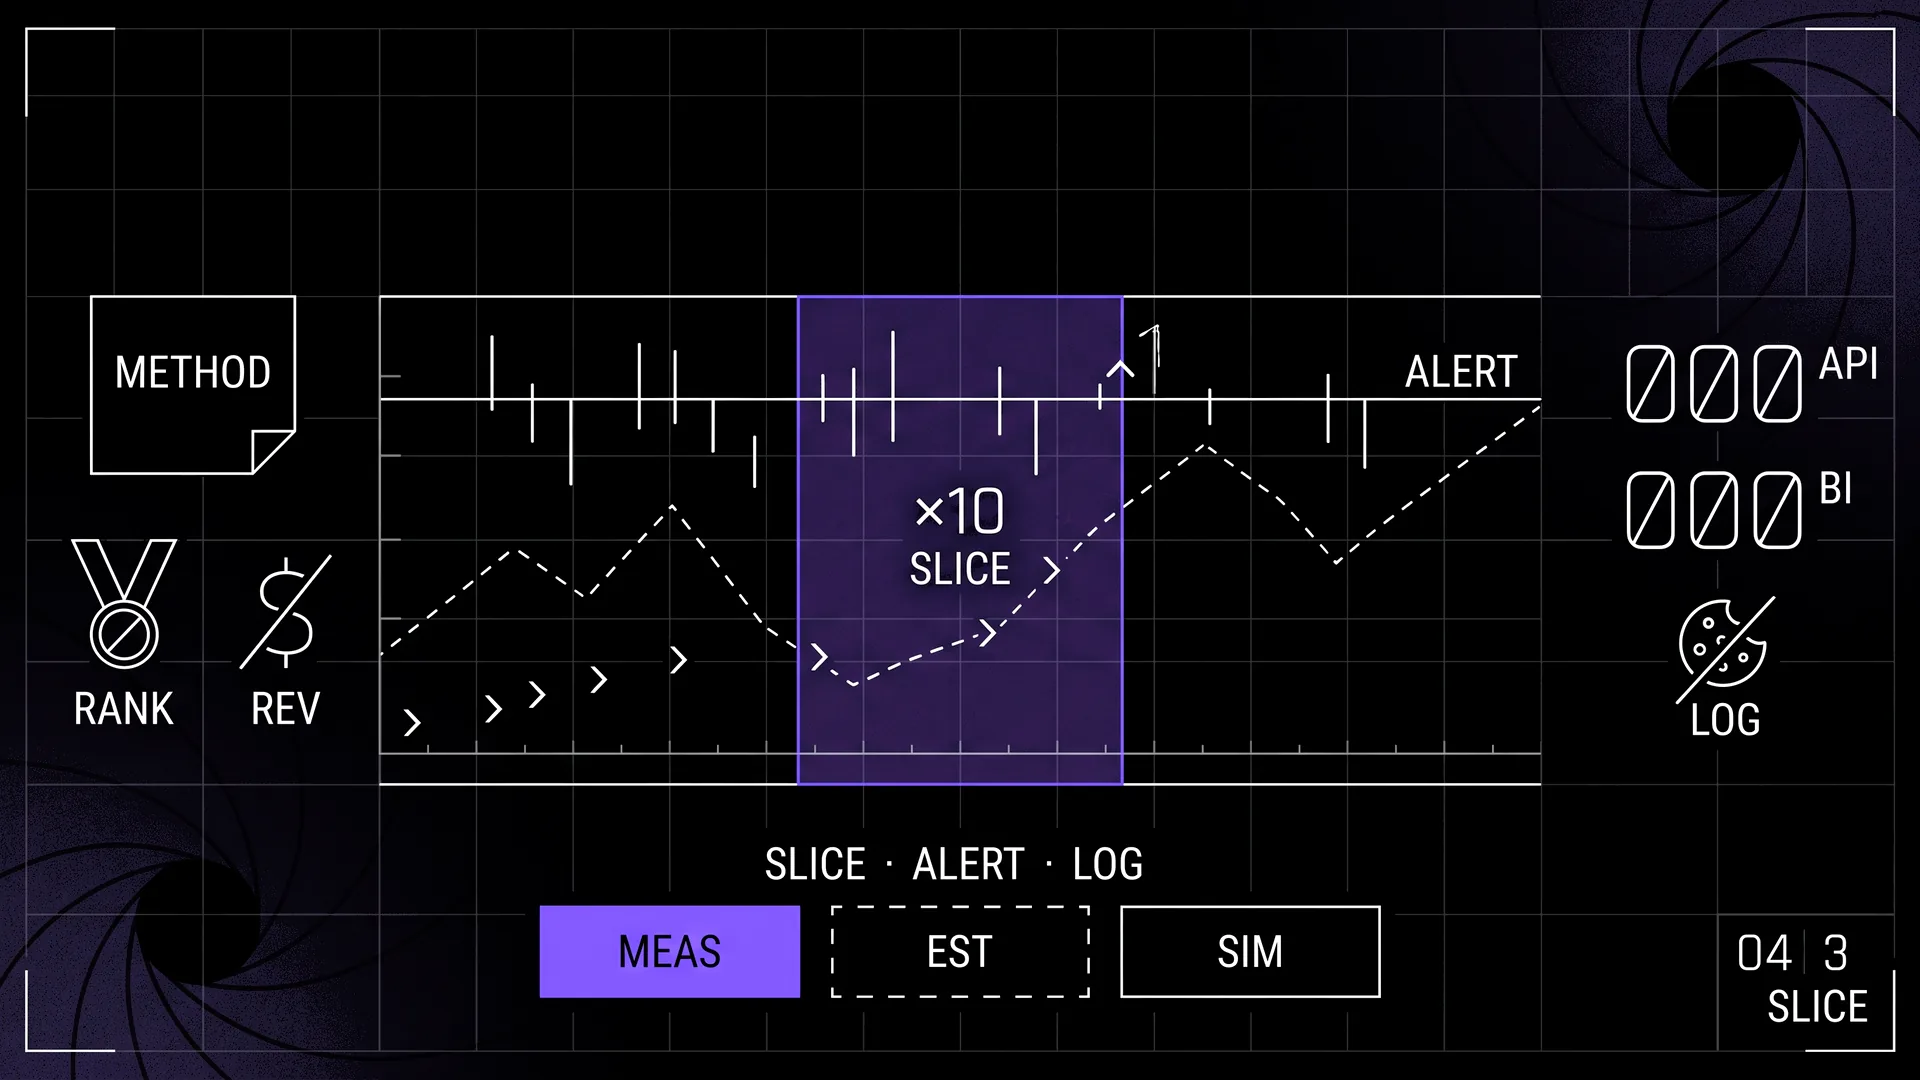
Strip-chart HUD: a monthly slice window over three traces, with alert, API, and BI.

Chat

Answers from your knowledge graph, on your site. Locale of the project — not the visitor’s GEO.

The widget cites URLs that already live in the graph. It does not invent publishers to sound complete. Origin is allowlisted. A short embed JWT is the only token in the page.

This is not a substitute for being named in ChatGPT. It is how your own site answers, once the facts are in the graph and a human has approved the source pages.

On the desk

  • On-site answers from the project graph
  • Citations that resolve to real URLs
  • Project locale, never the visitor’s country
  • Allowlisted origin and a short embed JWT
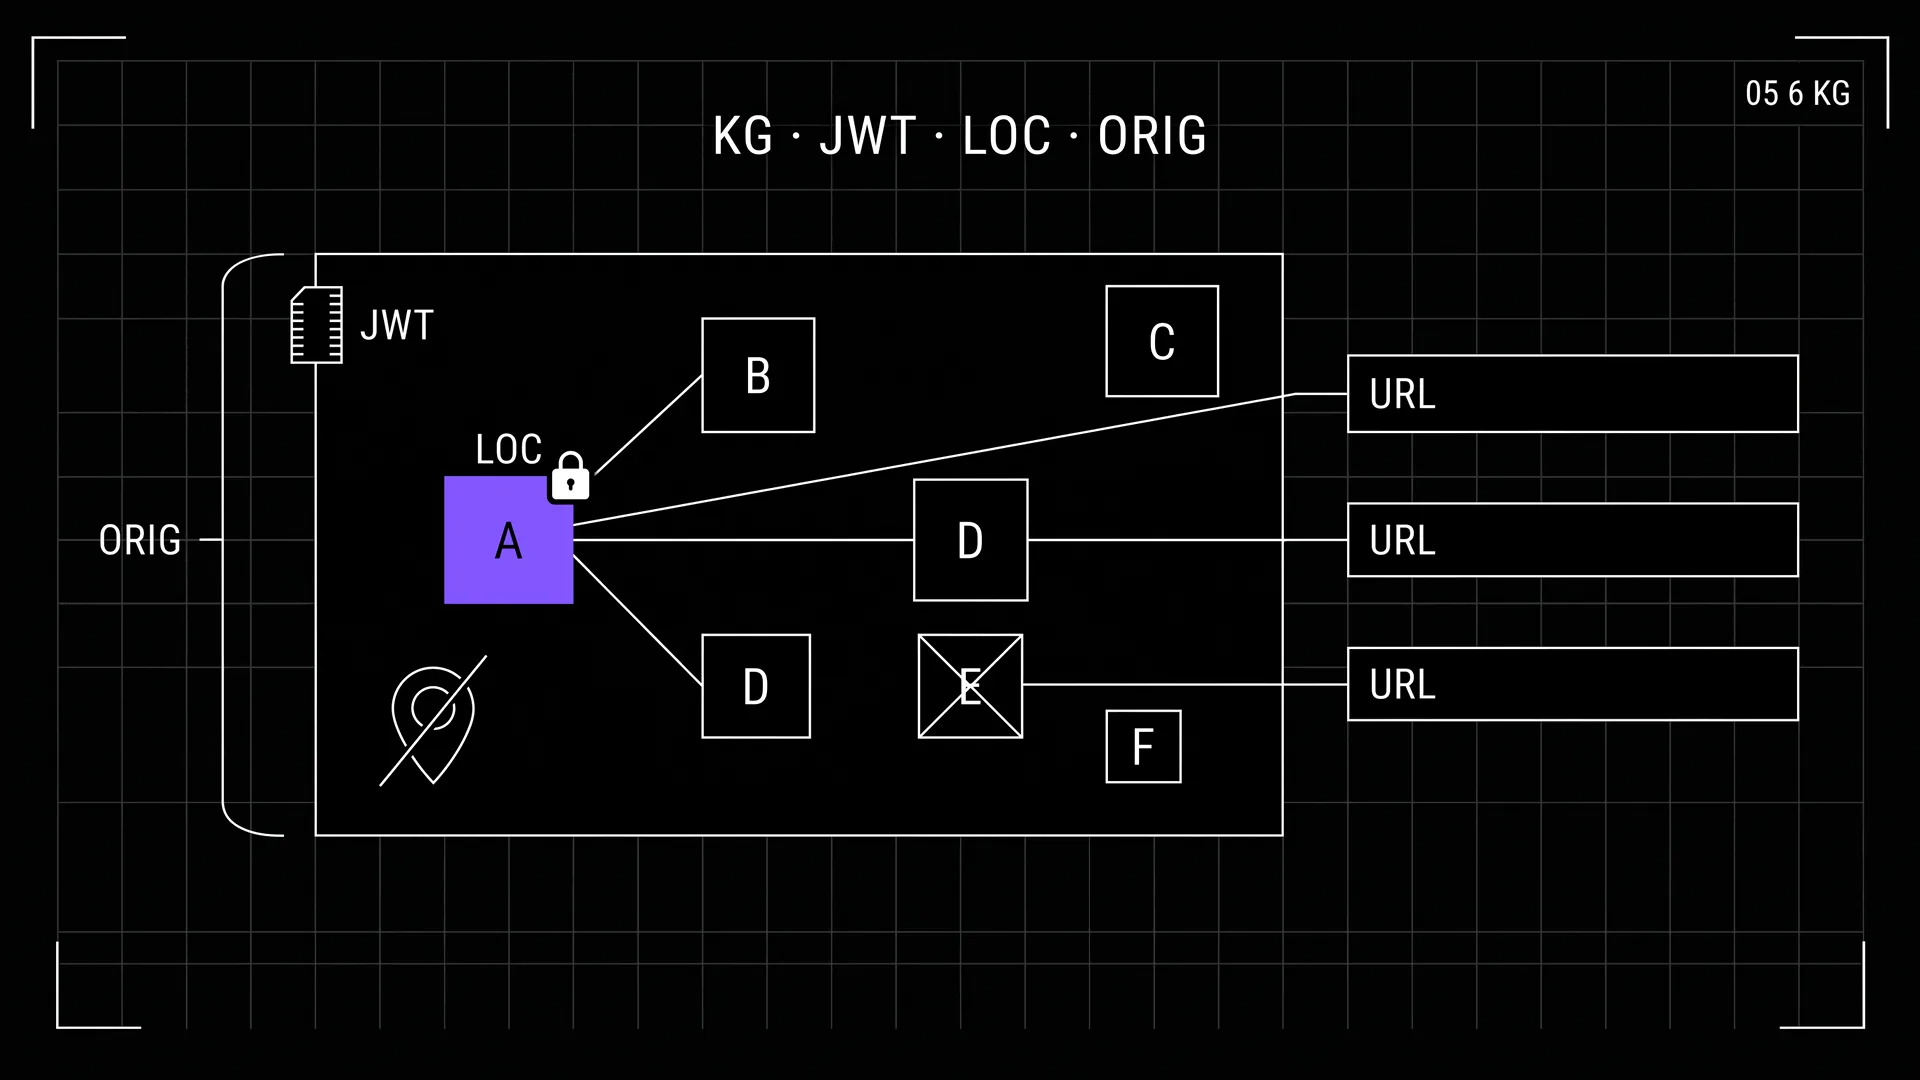
Widget-graph HUD: six nodes, citations ending in URL bars, locale locked, origin allowlisted.

Sales

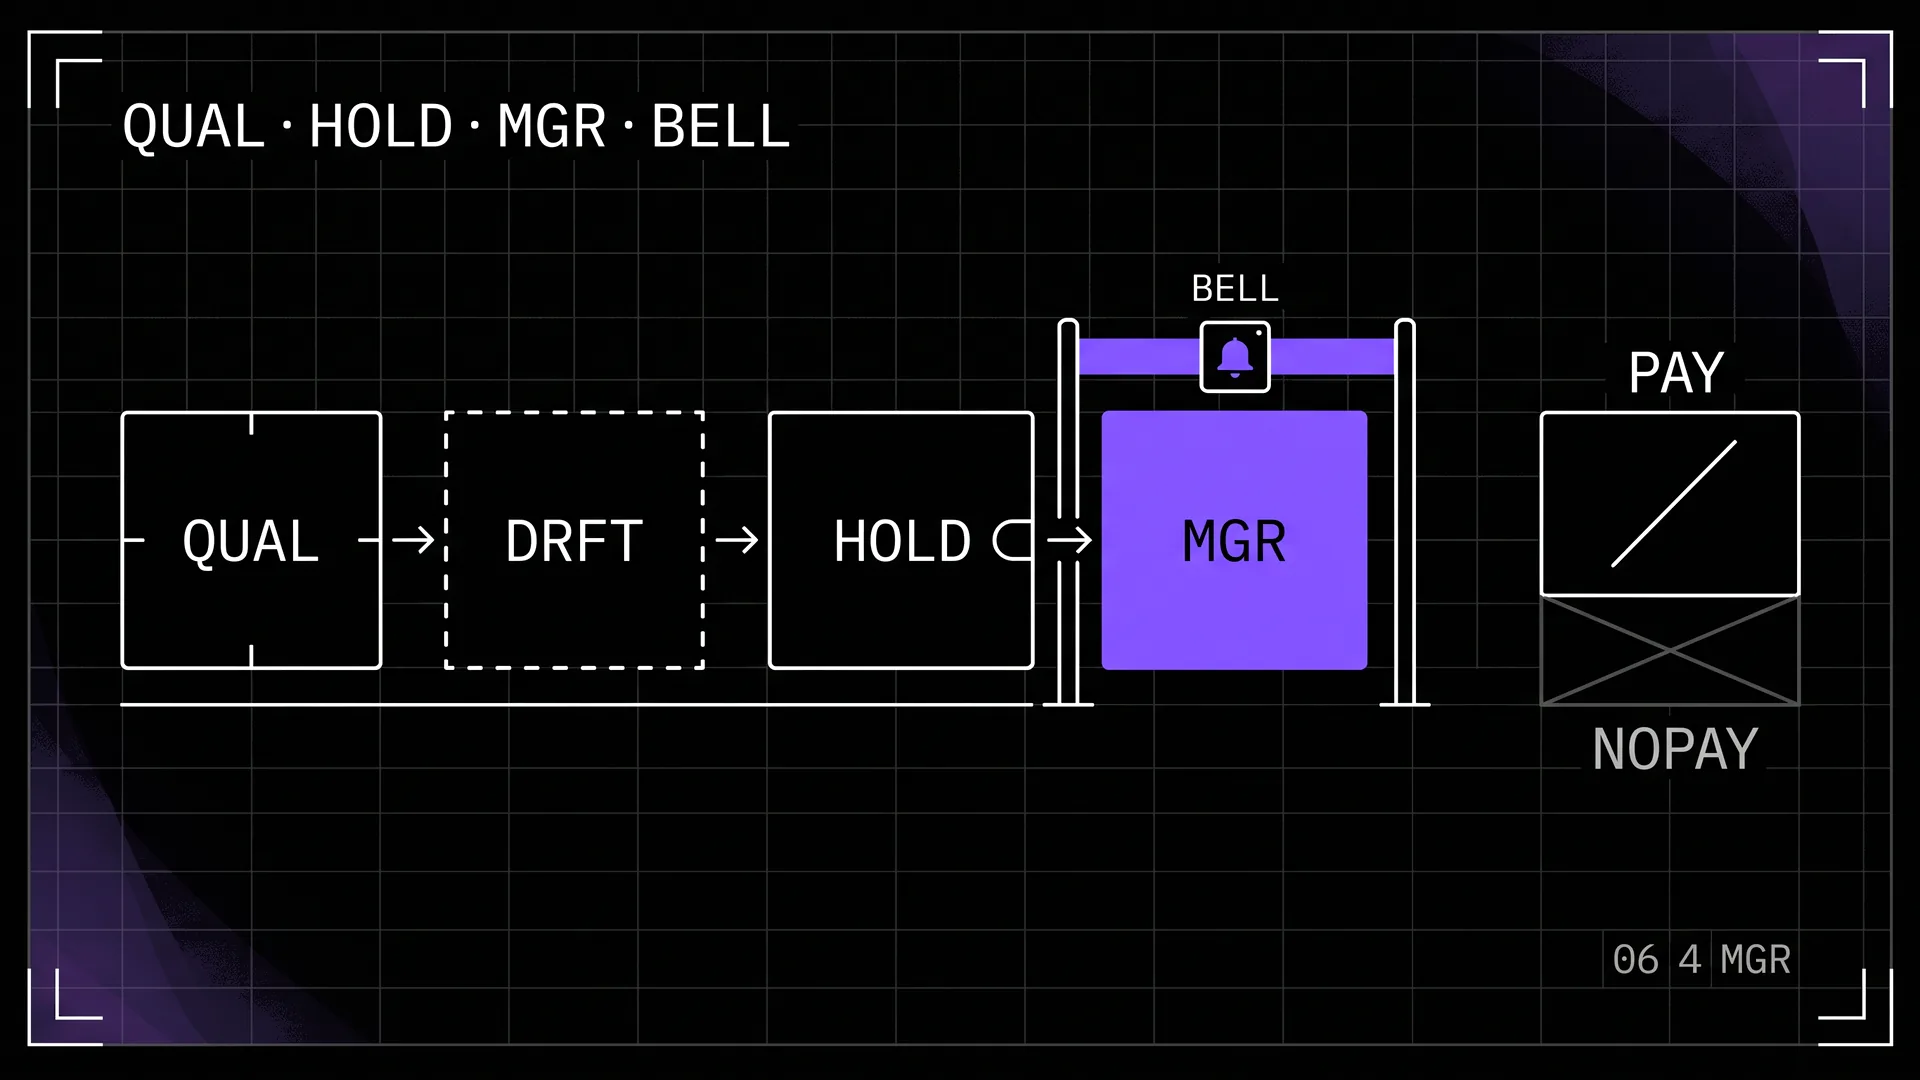
Human-in-the-loop tools for the close. Agents qualify. They do not charge.

Sales agents can draft a follow-up and hold a thread for a person. They must not take a card, open a portal, or sit on any future charge path. Payments stay out of v1 — by product law, not by delay.

A manager still writes back. The robot on Plans is a doorbell, not a checkout. That is the honest version of “talk to us.”

On the desk

  • Lead qualification with a human in the loop
  • Handoff to a manager — no charge
  • No LLM on any payment path
  • Plans as a conversation, not a cart
Handoff-queue HUD: qualify, draft, hold, then a manager bell — payment slashed.

Proof

Three columns. Never one fake rank.

The category sells “visibility.” We refuse to mash three different outcomes into a ChatGPT leaderboard. A monthly slice is a method. A screenshot is folklore.

  • Mention

    The brand name appears in the prose. Useful — and incomplete. Models name you while warning people off. Tone lives in a separate column.

  • Citation

    A URL the model names as a source. Owned, competitor, or earned. Citation share is not a vanity rank, and not a promise you will be linked next week.

  • Recommendation

    The model tells someone to use you. That is the outcome buyers actually want. It is rarer than a mention, and we keep it labelled.

Ten engines are surfaces, not a league table. ChatGPT is not Gemini Apps is not Perplexity. We name the surface. We do not sell a branded index.

When a number is an estimate or a simulation, the dashboard says so. Honesty badges travel with the slice. Mixing consumer UI with a model API into one score is how the category lies.

How it works

Audit. Access. Facts. Then measure again.

The loop is monthly on purpose. Stochastic answers need a frozen panel and a calendar, not a one-shot screenshot sold as a rank.


  1. Audit

    Same prompt set, ten named engines, a dated slice. Mention, citation, and recommendation stay apart so a meeting can read the page without a folklore slide.


  2. Bot access

    Let crawlers in. robots, llms.txt, sitemaps, headers. Same public HTML for people and bots — no cloaking, no UA-specific pages. Discover is not a citation guarantee.


  3. Extractable facts

    Pages a model can lift: dated, consistent, quotable. A human signs off before publish. FAQ spam is not a ranking trick here.

  4. Earn, then remeasure

    Pitch the publishers the model already cites. Slice again in a month. No guaranteed ChatGPT slot. No paid answer tile in v1.

Who it is for

Growth desks that outgrew ten blue links.

If your SEO is “fine” and the models still name a competitor, the channel is already leaking — before anyone hits your site.

  • Brand and growth teams

    You need to know how models describe you in the markets you actually sell — country, language, dialect — not a global average that hides the bid.

  • SEO and content leads

    You already own crawl, schema, and the CMS. GEO adds the answer layer: what to publish, what to fix, what to remeasure. Hygiene first. Then the slice.

  • Agencies

    Several client URLs, several markets, one account language. White-label packaging is roadmap. The measurement stack is what we run now.

Journal

How the work is named.

Three notes from the desk: what we measure, why bots are hygiene, and why a monthly slice beats a screenshot.

All ideas

Plans

Three ways in. No checkout.

Payments are out of v1. Cards open a plan stub — not a price, not Stripe.

HOME shows three names so a first visit stays readable. The talk-track on Plans has four volumes. Neither screen is a cart. A manager writes back.


  • Starter

    First visibility slice. Ten engines. Hygiene, not a rank ticket.

    • Prompt panel on ten named engines
    • Mention, citation, recommendation kept apart
    • File audit: robots, llms.txt, sitemaps
    • A backlog — not a ChatGPT promise
    See plan
  • Growth

    Monthly tracking plus pages engines can actually cite.

    • Repeated sampling so the slice is defensible
    • Competitors named on the same panel
    • AEO drafts with a human in the loop
    • Alerts when share moves
    See plan
  • Enterprise

    Markets, competitors, and a desk that runs the loop.

    • Market cells: country, language, script
    • Citation outreach on domains already cited
    • API and BI of the same numbers
    • A manager on the thread — still no checkout
    See plan